What Google Did After Crawling 100+ NewsBolts Pages: An Indexing Case Study

Google crawling a publisher's pages does not automatically mean those pages will be indexed, rank well, or generate meaningful search traffic.
That distinction became important in a NewsBolts indexing case study involving more than 100 pages. Google was able to discover and crawl a substantial set of NewsBolts articles, but crawling was only one stage of the process. The more important question was what happened after Google fetched the pages.
The case study points to a useful lesson for digital publishers: indexing and visibility are separate problems.

Google can discover a page, crawl it, process it, select a canonical, add it to the index, and still show it very little or not prominently at all in Search. Google itself says that an indexed URL is eligible to appear in Search, but indexing does not guarantee that the page will appear in search results or rank prominently.
For NewsBolts, this changes the SEO question.
The goal is not simply to get Google to crawl more articles.
The goal is to make the pages discoverable, indexable, useful, differentiated, internally connected, and competitive for specific search intents.
Case-study note: This article explains the NewsBolts observation and the Google indexing process without inventing URL-level crawl dates, index counts, ranking positions, or Search Console measurements that are not publicly documented here. Where exact first-party measurements are required, they should be taken directly from NewsBolts Search Console.
The NewsBolts Indexing Case Study
The starting point was straightforward.
NewsBolts had published a growing library of articles covering:
AI news intelligence
newsroom automation
human-governed AI
editorial workflows
SEO
GEO
AEO
content repurposing
newsroom architecture
publisher economics
AI-assisted journalism
Google discovered and crawled more than 100 NewsBolts pages.
At first glance, that sounds like an indexing success.
But crawling is not the same thing as indexing.
And indexing is not the same thing as ranking.
This three-stage distinction is the most important lesson from the case study.
Crawl
Googlebot retrieves the page and examines its content, links, resources, and other signals.
Index
Google processes the page and may add it to its search index, potentially selecting a canonical version.
Search Visibility
The indexed page may then become eligible to appear for relevant queries, but its actual visibility depends on Google's search systems and many other factors.
Google describes Search as a process involving crawling, indexing, and serving. The fact that Google can access a page does not mean that the page will necessarily be indexed or prominently served.
That distinction explains why a publisher can look technically healthy while still seeing weak search impressions.
What Happened After Google Crawled the Pages?
The important finding was not simply that Google crawled NewsBolts pages.
The more useful observation was that Google's crawl activity did not automatically translate into strong search visibility.
That is exactly the type of situation publishers often misunderstand.
A page can be:
Crawled → Indexed → Low visibility
There is nothing contradictory about this.
Google's own Search Console documentation states that an indexed URL is eligible to appear in Search but is not guaranteed to appear.
The Page Indexing documentation also warns publishers not to assume that every URL should be indexed. Google recommends focusing on important canonical pages rather than trying to achieve 100% indexing coverage.
For NewsBolts, that meant the next SEO question was not:
"Why isn't Google crawling us?"
It became:
"What happens to our pages after Google crawls them?"
That is a much better diagnostic question.
Crawling 100+ Pages Was Not the Same as Winning Search Visibility
This is where many publishers make a strategic mistake.
They see evidence that Googlebot has visited their site and conclude that SEO should now improve automatically.
It does not work that way.
Imagine three hypothetical pages:
Page | Crawled | Indexed | Search Visibility |
Page A | Yes | Yes | Strong |
Page B | Yes | Yes | Limited |
Page C | Yes | No | None |
All three pages were crawled.
Their outcomes are completely different.
This is why Search Console should be analyzed as a series of related reports rather than one "indexed/not indexed" number.
What Google Checks After Crawling a Page
After discovering and crawling a URL, Google needs to process what it found.
Among the important questions are:
Can Google access the content?
Is the page indexable?
Is there a noindex directive?
Is the page a duplicate?
What canonical URL should represent the content?
Does the page contain meaningful content?
Is the content accessible to Google?
Does the page provide useful information?
How does it relate to other pages?
Is there evidence that another URL should be canonical instead?
The URL Inspection tool provides information about Google's indexed version of a specific page, including discovery, crawling, indexing, and the canonical Google selected.
That makes URL Inspection particularly useful for a case study like NewsBolts.
Instead of asking whether Google "likes" the site, the publisher can inspect individual pages and determine what Google actually knows about them.
The First Lesson: Google Can Crawl a Page Without Indexing It
Google explicitly says that crawling does not guarantee indexing.
Its Search Console documentation notes that a new page can take time to be discovered and crawled, and even after Google knows a URL, indexing is not guaranteed.
Google also identifies several reasons a known URL may remain outside the index, including:
noindex
duplicate content
canonical selection
inaccessible pages
soft 404s
technical problems
pages Google considers unsuitable for indexing
This means the first step in an indexing case study should always be classification.
For every important page, determine whether the status is:
Indexed
Crawled – currently not indexed
Discovered – currently not indexed
Duplicate
Blocked
Error
or another Search Console status.
Without this classification, publishers can easily spend time fixing the wrong problem.
The Second Lesson: Indexing Does Not Guarantee Impressions
This was the more important NewsBolts lesson.
Even when pages become indexed, visibility can remain limited.
Google's documentation is explicit about this.
An indexed page is eligible to appear in Search, but indexing does not guarantee that it will show up for a particular query.
That means a publisher can have:
Technical indexing success
without having:
Search performance success.
This distinction matters enormously for NewsBolts.
If a page is indexed but receives very few impressions, repeatedly requesting indexing is unlikely to solve the underlying visibility problem.
The publisher should instead investigate:
search intent
query demand
topic specificity
content differentiation
internal linking
topical authority
competition
page quality
title relevance
entity clarity
original value
external authority
Indexing gets the page into the race.
It does not make the page win the race.
The Third Lesson: A Sitemap Helps Discovery, Not Guaranteed Indexing
Another important part of the NewsBolts case study is the role of the sitemap.
A sitemap gives Google information about URLs that the publisher considers important.
But a sitemap is not an indexing command.
Google's documentation says there is no guarantee that URLs discovered through a sitemap will be crawled or indexed.
Google also recommends using sitemaps to help communicate pages that should be discovered, particularly when there are many pages.
For NewsBolts, the practical approach is therefore:
Publish → internally link → include in sitemap → allow crawling → monitor Search Console
rather than:
Publish → submit sitemap → expect ranking
The sitemap is part of the discovery infrastructure.
It is not a ranking shortcut.
The Fourth Lesson: Internal Links Matter After Discovery
A sitemap can tell Google that a URL exists.
Internal links help establish how that URL fits into the site's content structure.
This matters especially for NewsBolts because the site covers a specialized subject area.
Consider the relationship between:
AI Newsroom
→ AI News Intelligence
→ Newsroom Architecture
→ Human Editorial Governance
→ AI-Assisted Writing
→ Article-to-Reel Automation
→ Publisher Economics
These are not isolated subjects.
They form a knowledge structure.
When articles link to relevant parent and sibling pages, Google can more easily discover relationships between topics.
It also helps users move from one piece of information to another.
This is why NewsBolts should not treat every article as an independent SEO asset.
Each article should have:
a parent topic
related sibling articles
relevant supporting pages
a clear next-step page
The crawl may discover the URLs.
The internal-link structure helps explain the site's architecture.
What the NewsBolts Content Pattern Revealed
The indexing case study also exposed a broader SEO issue.
NewsBolts was publishing many articles around closely related AI newsroom concepts.
That creates an opportunity for topical authority.
But it also creates a potential overlap problem.
For example, a publisher could have several articles covering:
AI newsroom
AI newsroom operating system
AI newsroom architecture
human-governed AI newsroom
AI newsroom automation
autonomous newsroom
AI newsroom technology stack
These topics are related, but Google still needs to understand what each page uniquely contributes.
If several pages target almost the same intent, the publisher may be creating a collection of pages without clearly defining the role of each one.
That does not mean related articles are bad.
It means they need distinct search intent and stronger internal relationships.
The Difference Between Topical Depth and Topic Repetition
This is one of the most important lessons from the NewsBolts experience.
Publishing 20 articles about AI newsrooms does not automatically create 20 independent ranking opportunities.
A better strategy is to build a topic cluster.
For example:
Pillar
AI Newsroom Operating System
Supporting Topics
AI News Intelligence
Human-Governed AI Newsroom
AI-Assisted News Writing
AI Newsroom Architecture
AI Newsroom Technology Stack
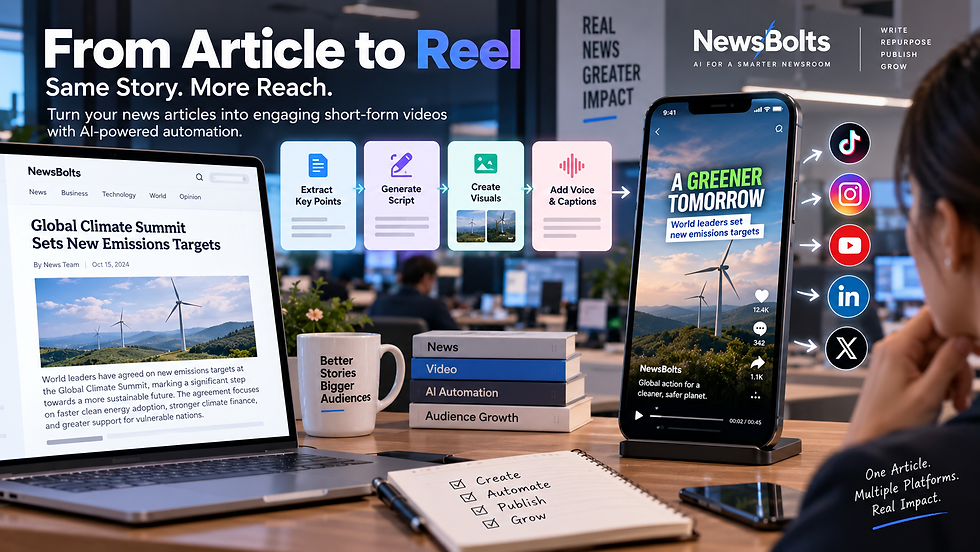
Article-to-Reel Automation
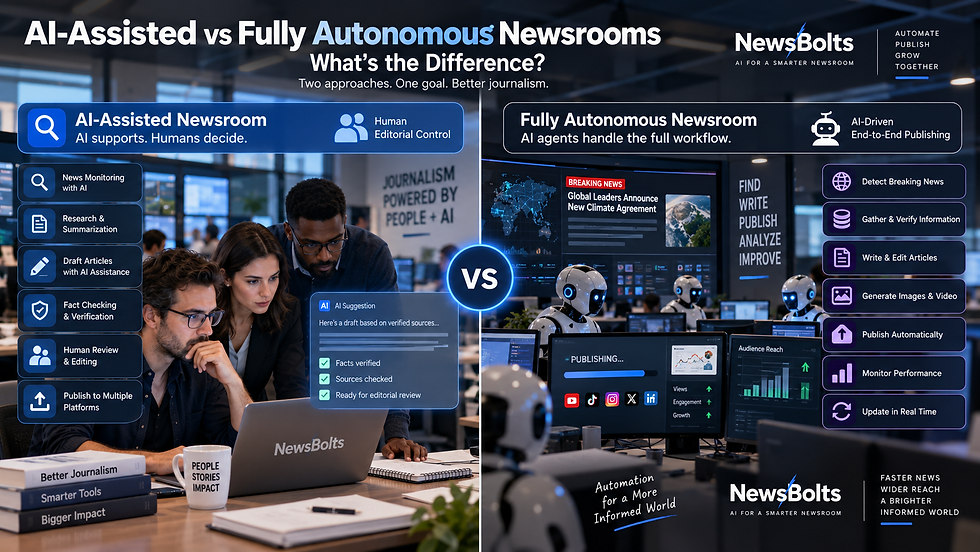
AI-Assisted vs Fully Autonomous Newsrooms
Now each page has a clearer role.
The pillar explains the system.
Supporting pages explain individual components.
The result is a connected knowledge structure rather than a collection of similar articles.
NewsBolts already has pages covering several of these subjects, including its AI newsroom operating system, AI news intelligence, human-governed newsroom, and AI newsroom architecture.
The next step is not necessarily publishing more pages.
It is strengthening the relationships between them.
What Google Search Console Should Be Used to Measure
The NewsBolts case study should be evaluated through several Search Console signals.
1. Indexed Pages
How many important canonical URLs are actually indexed?
2. Crawled but Not Indexed
Are certain content types repeatedly being crawled without entering the index?
3. Impressions
Are indexed pages beginning to appear for searches?
4. Clicks
Are impressions turning into visits?
5. CTR
Are searchers selecting NewsBolts when pages appear?
6. Queries
What topics and phrases are generating visibility?
7. Pages
Which URLs are receiving the visibility?
8. Average Position
How does visibility change over time?
Google's Search Console Performance reporting provides clicks, impressions, CTR, and average position, with dimensions such as queries and pages. These metrics should be analyzed together rather than treating position as the only indicator of progress.
For the NewsBolts case study, this creates a much better measurement model:
Crawl → Index → Impression → Click → Engagement
Each stage answers a different question.
How to Diagnose the Problem Correctly
Suppose a NewsBolts page has been crawled.
The next diagnostic process should look like this.
Scenario 1: Not Crawled
Focus on:
discoverability
internal links
sitemap
technical accessibility
Scenario 2: Crawled but Not Indexed
Focus on:
indexability
duplicate/canonical issues
content quality
page usefulness
technical problems
whether the URL deserves independent indexing
Scenario 3: Indexed but Almost No Impressions
Focus on:
keyword targeting
search demand
topic specificity
competition
content differentiation
internal linking
authority
Scenario 4: Impressions but Few Clicks
Focus on:
title
snippet relevance
search intent
page positioning
content promise
Scenario 5: Impressions and Clicks but Weak Business Value
Focus on:
conversion
newsletter signup
product interest
returning users
commercial intent
content-to-product alignment
This framework prevents the common mistake of treating every SEO problem as an indexing problem.
What NewsBolts Should Do After 100+ Pages Are Crawled
The case study points toward a different publishing strategy.
The next stage should not be:
Publish another 100 articles.
It should be:
Understand the 100+ pages already discovered by Google.
Start by classifying them.
Group 1: Strong Pages
These have:
clear intent
useful content
impressions
clicks
strong internal links
Keep improving them.
Group 2: Indexed but Weak
These deserve analysis.
Ask:
Is the keyword too broad?
Is the article targeting the wrong intent?
Does another NewsBolts article cover the same topic?
Is there enough original value?
Does the title match what people search for?
Does the page need stronger internal links?
Group 3: Similar or Overlapping Pages
These may need consolidation, clearer differentiation, or stronger hierarchy.
Group 4: Weak Pages
If a page has little strategic value and overlaps with stronger content, it may not deserve additional investment.
This is more useful than chasing a perfect indexing percentage.
Google itself says publishers should not expect every URL to be indexed and recommends focusing on important canonical pages.
What the Case Study Does Not Prove
An honest case study also needs limitations.
The fact that Google crawled 100+ NewsBolts pages does not prove that:
Google considers the site authoritative
every page will be indexed
every indexed page will rank
publishing more pages will increase traffic
crawl frequency causes ranking improvements
requesting indexing improves rankings
a sitemap increases rankings
AI content automatically receives lower rankings
Google has a fixed "trust score" for NewsBolts
Those conclusions would require stronger evidence.
The correct interpretation is narrower:
Google can discover and process NewsBolts content, but the next SEO challenge is turning discovery and indexing into meaningful search visibility.
That is a much more defensible conclusion.
Why "Indexed" Should Not Be the Main SEO Goal
Publishers sometimes treat an indexing percentage as the main success metric.
That can create the wrong incentives.
Imagine a publisher has 1,000 indexed pages and receives almost no search traffic.
Another publisher has 300 indexed pages but receives substantial impressions and clicks from highly relevant searches.
The second publisher may have the stronger search strategy.
Google's own documentation makes this point indirectly by recommending that publishers focus on important pages rather than trying to force 100% index coverage.
For NewsBolts, the objective should therefore become:
Fewer stronger pages with clearer topic relationships and measurable search demand.
Not simply:
More indexed URLs.
A Better NewsBolts Indexing Workflow
NewsBolts can turn this case study into a repeatable process.
Step 1: Publish
Create a genuinely useful article around a defined publisher problem.
Step 2: Make the Page Crawlable
Check:
HTTP status
robots.txt
noindex
canonical
accessible content
internal links
Step 3: Add to the Sitemap
Make sure the canonical URL is appropriately represented.
Step 4: Create Internal Links
Connect the article to:
its parent pillar
related articles
relevant next-step content
Step 5: Inspect the URL
Use Search Console to understand discovery, crawl, indexing, and canonical information.
Step 6: Monitor Indexing
Do not assume that submission equals indexing.
Step 7: Monitor Search Performance
Track:
impressions
clicks
CTR
queries
pages
Step 8: Improve the Page
If the page is indexed but weak, optimize the content rather than repeatedly requesting indexing.
Step 9: Strengthen the Cluster
Add contextual links and improve the parent topic.
Step 10: Consolidate When Necessary
If several pages compete for the same intent, decide whether they should be differentiated or consolidated.
This workflow turns indexing into an ongoing publishing process instead of a one-time technical task.
The Bigger Lesson for Digital Publishers
The NewsBolts case study is really about a shift in SEO thinking.
Older SEO workflows often focused heavily on:
Can Google find the page?
That remains important.
But modern publishing requires additional questions:
Does the page deserve to be indexed?
What search intent does it satisfy?
How is it different from our other pages?
What evidence supports the article?
Where does it sit within the site's topic structure?
Does it earn impressions?
Does it earn clicks?
Does it create value for the reader?
Google's current documentation makes clear that indexing is only one stage of Search. The URL Inspection tool can show how Google discovered and crawled a URL, what canonical it selected, and whether it is in the index, but being "on Google" still does not guarantee search visibility.
For publishers, that distinction is critical.
What Publishers Should Do
If Google has crawled hundreds of pages on a publishing site, do not immediately respond by producing hundreds more.
First, analyze what Google already knows.
Create an indexing and visibility inventory containing:
Question | What to Check |
Can Google discover it? | Links, sitemap |
Can Google crawl it? | Access, robots, server response |
Can Google index it? | noindex, canonical, content |
Is it indexed? | Search Console |
Does it receive impressions? | Performance report |
Does it receive clicks? | Performance report |
Is the intent clear? | Query and page analysis |
Does it overlap? | Topic-cluster review |
Does it have internal links? | Site architecture |
Does it provide original value? | Editorial review |
Then prioritize the pages that can realistically become valuable search assets.
For NewsBolts, this means moving from a publishing-volume strategy toward a topical-authority and content-quality strategy.
The site's AI newsroom focus is not the problem.
The opportunity is to make that focus more structured.
NewsBolts Research Opportunity: The 100+ Page Indexing Benchmark
This case study could become a stronger first-party research asset if NewsBolts records the actual URL-level data over time.
A proper NewsBolts Indexing Benchmark could track:
URL
publication date
topic cluster
word count
internal links
sitemap inclusion
first discovered date
first crawl date
indexed date
canonical selected
impressions after 7 days
impressions after 30 days
clicks after 30 days
primary query
average position
content type
update history
The research question could then become:
What happens to NewsBolts pages during the first 30, 60, and 90 days after publication?
That would be much more valuable than another generic SEO article.
It could reveal whether certain topic clusters are discovered faster, whether internal links influence discovery, which content types become indexed, and which indexed pages actually develop search visibility.
But those findings should only be published after the data has been collected.
Frequently Asked Questions
Does Google Crawling a Page Mean It Is Indexed?
No. Crawling and indexing are separate stages. Google can crawl a page and still decide not to include it in its index. Search Console provides separate information about crawling and indexing status.
How Long Does Google Take to Index a News Publisher's Page?
There is no guaranteed indexing time. Google says indexing can take several days or longer in some cases, and requesting indexing does not guarantee inclusion.
Does Requesting Indexing Guarantee Rankings?
No. A request asks Google to consider crawling or indexing a URL. It does not guarantee indexing, ranking, or search visibility.
Why Can an Indexed News Article Have Almost No Impressions?
Indexing only makes a page eligible to appear. Limited impressions can result from low search demand, broad or unclear intent, strong competition, weak differentiation, limited authority, poor internal linking, or other search factors.
Should Publishers Try to Get Every Page Indexed?
No. Google explicitly says publishers should not expect every URL to be indexed and should focus on important canonical pages. Duplicate, obsolete, or low-value URLs may appropriately remain outside the index.
Does a Sitemap Guarantee Indexing?
No. Google says URLs discovered through a sitemap are not guaranteed to be crawled or indexed. A sitemap is primarily a discovery and communication mechanism.
What Should NewsBolts Do With Indexed Pages That Get Few Impressions?
The next step should be content and search analysis rather than repeatedly requesting indexing. Review search intent, query demand, topical overlap, internal links, title relevance, content differentiation, and the page's role within the NewsBolts topic cluster.
Is Indexing the Same as Ranking?
No. Indexing means Google has included the page in its index and the page may be eligible to appear. Ranking determines where and when it appears for particular searches. Google explicitly notes that being indexed does not guarantee search visibility.
Can Publishing More Articles Increase NewsBolts Impressions?
More publishing does not automatically increase impressions. Additional pages can help when they satisfy valuable search intents and strengthen topical coverage, but publishing overlapping or low-value pages can dilute editorial resources and create unnecessary complexity.
Conclusion
The most important lesson from the NewsBolts 100+ page indexing case study is simple:
Google crawling a page is only the beginning.
The real SEO journey continues through discovery, crawling, indexing, search eligibility, impressions, clicks, and eventually meaningful audience value.
NewsBolts therefore should not treat Google's crawl activity as proof that its SEO strategy is working.
It should treat crawling as evidence that Google can discover and process the site—and then investigate what happens next.
The strongest strategy is to:
monitor important URLs
understand indexing states
strengthen internal links
build clear topic clusters
differentiate related articles
improve search intent targeting
create original publisher-focused information
measure impressions and clicks
update pages based on evidence
consolidate unnecessary overlap
The lesson is especially important for an AI newsroom publisher.
AI makes it easier to produce content at scale.
That makes content selection, differentiation, verification, and information architecture more important not less.
NewsBolts does not need to prove that it can publish hundreds of AI newsroom articles.
It needs to prove that each important page has a clear reason to exist.
Google can crawl a hundred pages.
The real SEO achievement is building a site where Google and more importantly, readers can understand why those pages matter.
Comments